 Flock Bio ↗
Finding leads by what they post, not their job title
01
Why searching by job title does not work
- No job title tells you who is about to build a DNA library. Searching by title and company returns thousands of people, and almost none of them have the problem right now.
- The audience is small enough that burning it with generic outreach cannot be undone. There is no second list.
- What someone posted about last week does tell you. It is the only signal available that shows what they are working on rather than what they are called.
02
How it works
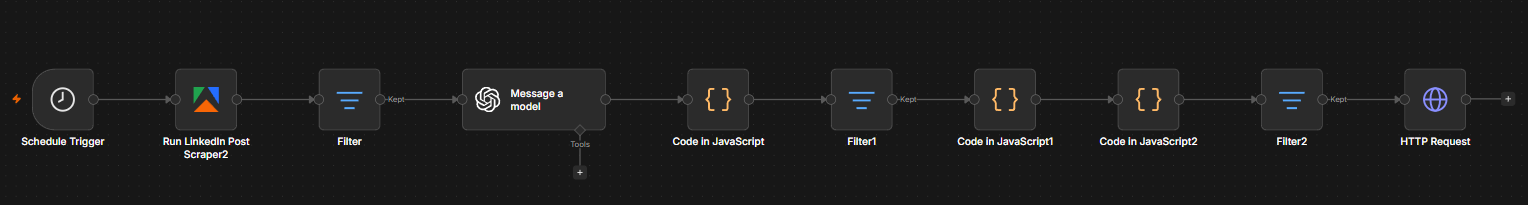
Fig 1 Finding the posts, then the people who engaged with them
Approved leads move from the Google Sheet into HeyReach every 3 days.
An LLM cleans up the names first, stripping titles and credentials, because “Hi Dr. Sarah Chen PhD” instantly reads as automation.
Fig 2 Two different openers, depending on who they are
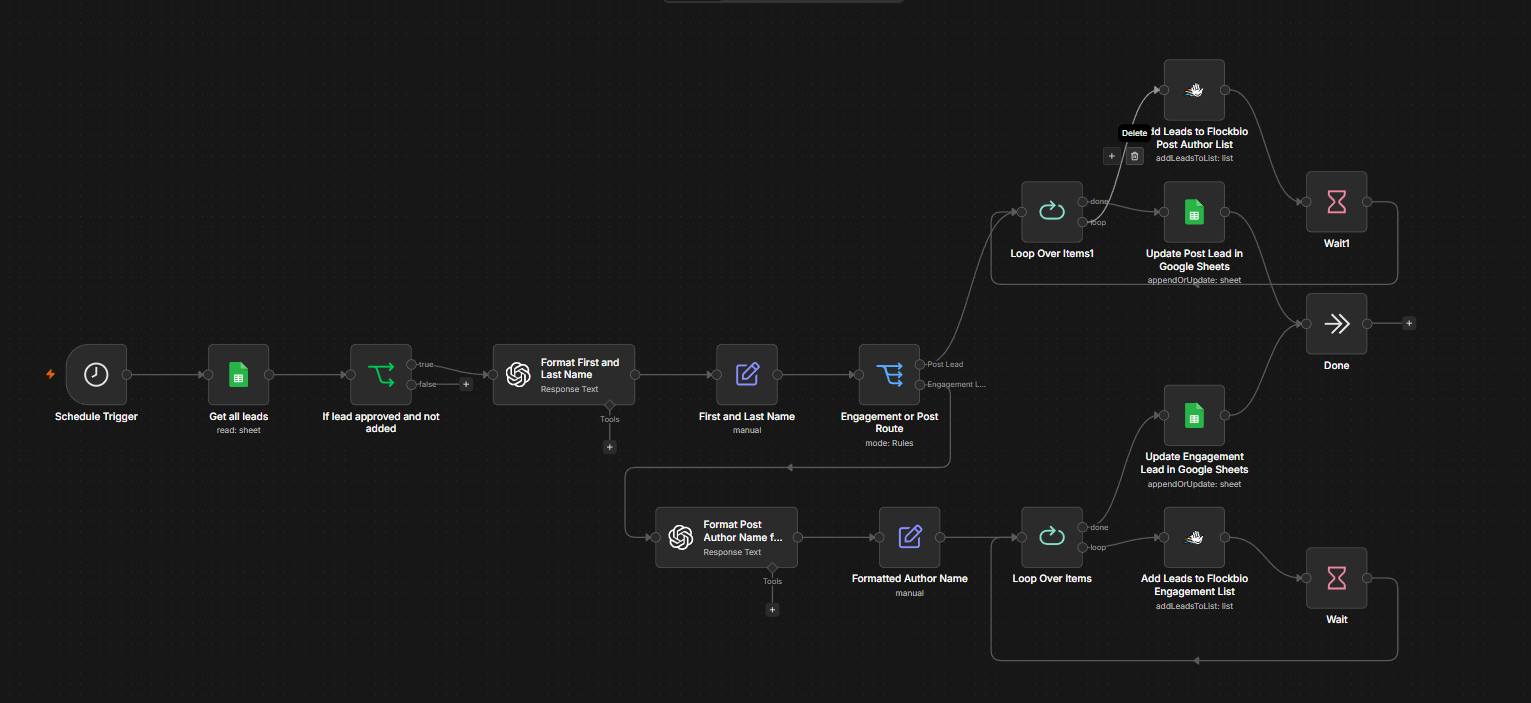
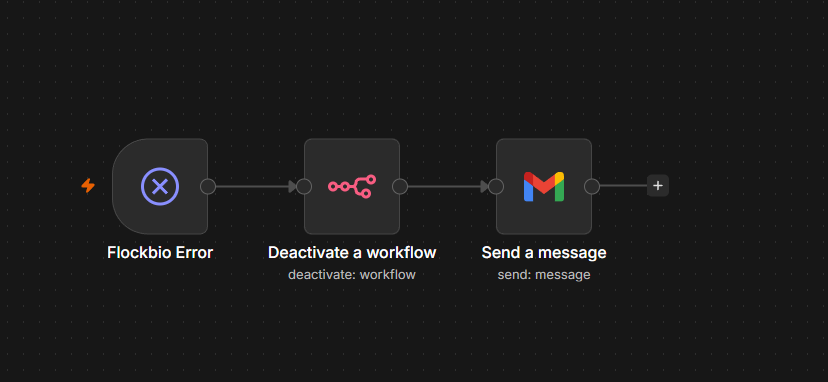
Fig 3 What happens when something breaks
03
Results
42.6%message reply rate
78.5%connection acceptance
20replies from 47 messages
3 daysbetween sending runs
One month of an ongoing campaign: 65 connection requests, 51 accepted, 47 messages, 20 replies. Those replies became booked meetings, which is the number that matters to them.
Stack
 Apify
 n8n
 Clay
 HeyReach
More work
If any of this is the shape of your problem, I’d like to hear about it.
Eastern time, New Jersey, US
Client names and internal details omitted where I am under confidentiality.